You've set up an ambitious outbound calling campaign with different scripts for various customer segments. After weeks of calls, you check your data and think you've found a winning strategy for high-value prospects. But when you implement it broadly, the results fall flat. What went wrong? You may have fallen into the multi-segment testing trap, where the more segments you test, the higher your chances of drawing false conclusions.
This challenge is amplified when you're starting from scratch with no existing conversion rate benchmark, dealing with limited staff capacity, or struggling with data quality issues. As one sales leader confessed on Reddit, "I'm concerned that testing conversion rates across many segments at the same time may lead to inaccurate conclusions."
In this article, we'll provide a framework for maintaining statistical validity when testing conversion rates across multiple customer segments simultaneously, with a particular focus on the constraints of outbound calling campaigns.
Statistical significance in a sales context acts as your "truth detector." It tells you if the difference in conversion rates between two sales strategies (like different call scripts) is real or just due to random chance. Typically, we use a significance level (alpha) of 5% (0.05), meaning we're 95% confident that our observed results aren't a fluke.

This sounds reasonable for a single test. But here's where the trap lies: when you test across multiple segments, your risk compounds dramatically.
Critical Insight: When you run 10 separate tests (e.g., across 10 customer segments) at a 95% confidence level, your chance of getting at least one false positive skyrockets to 40%!
This happens because each segment you test is essentially a new experiment. Without correcting for this multiplicity, you're very likely to act on misleading results, potentially wasting resources on ineffective strategies.
Even more dangerous is "data dredging" or post-test segmentation—analyzing results by customer segments after a test has concluded. This practice, also known as "p-hacking," dramatically increases the risk of false positives because you're effectively running multiple tests retroactively, looking until you find something that appears significant.
Before launching any multi-segment sales test, you need to conduct a power analysis—a statistical calculation that determines your experiment's ability to detect a meaningful effect if one truly exists.
Power analysis helps you avoid Type II errors (false negatives)—failing to detect a real difference between your control group and focal group. Industry standard is to aim for a statistical power of 0.8 (or 80%), meaning you have an 80% chance of detecting a true effect if it exists.
A proper power analysis depends on four key elements:
The MDE is particularly crucial in sales contexts. It answers the question: "How small a difference in conversion rate do we need to reliably detect for this test to be worthwhile?" For example, if your current conversion rate is 10%, and a 2% absolute increase (to 12%) would significantly impact your LTV calculations, then your MDE is 2%.
Practical Steps for Conducting a Power Analysis:
For example, if your baseline conversion rate is 10% and you want to detect a 3% absolute increase (to 13%), with 80% power and 95% confidence, you'll need approximately 700 prospects per test group. This calculation is crucial because it helps you determine if you have enough prospects to run a valid test across multiple segments.

The most important rule in multi-segment testing is to define your segments before the test begins. This segmenting should be based on historical data or clear business logic (e.g., high LTV clients, industry verticals, or prospective customers with specific needs).
Pre-segmentation prevents "data dredging" and ensures you're testing a specific, pre-defined hypothesis for each segment. For outbound calling campaigns, this might mean creating distinct call lists for each segment before any calls are made.
When testing across multiple segments, you need to implement a correction to counteract the multiple comparisons problem. The Bonferroni correction is a simple but effective method:
Example: If your α is 0.05 and you're testing across 5 customer segments, your new, corrected significance level is 0.05 ÷ 5 = 0.01. For any single segment, the result is only considered statistically significant if the p-value is less than 0.01.
This correction makes it harder to get a significant result, but it protects you from false positives that could lead to implementing ineffective sales strategies.

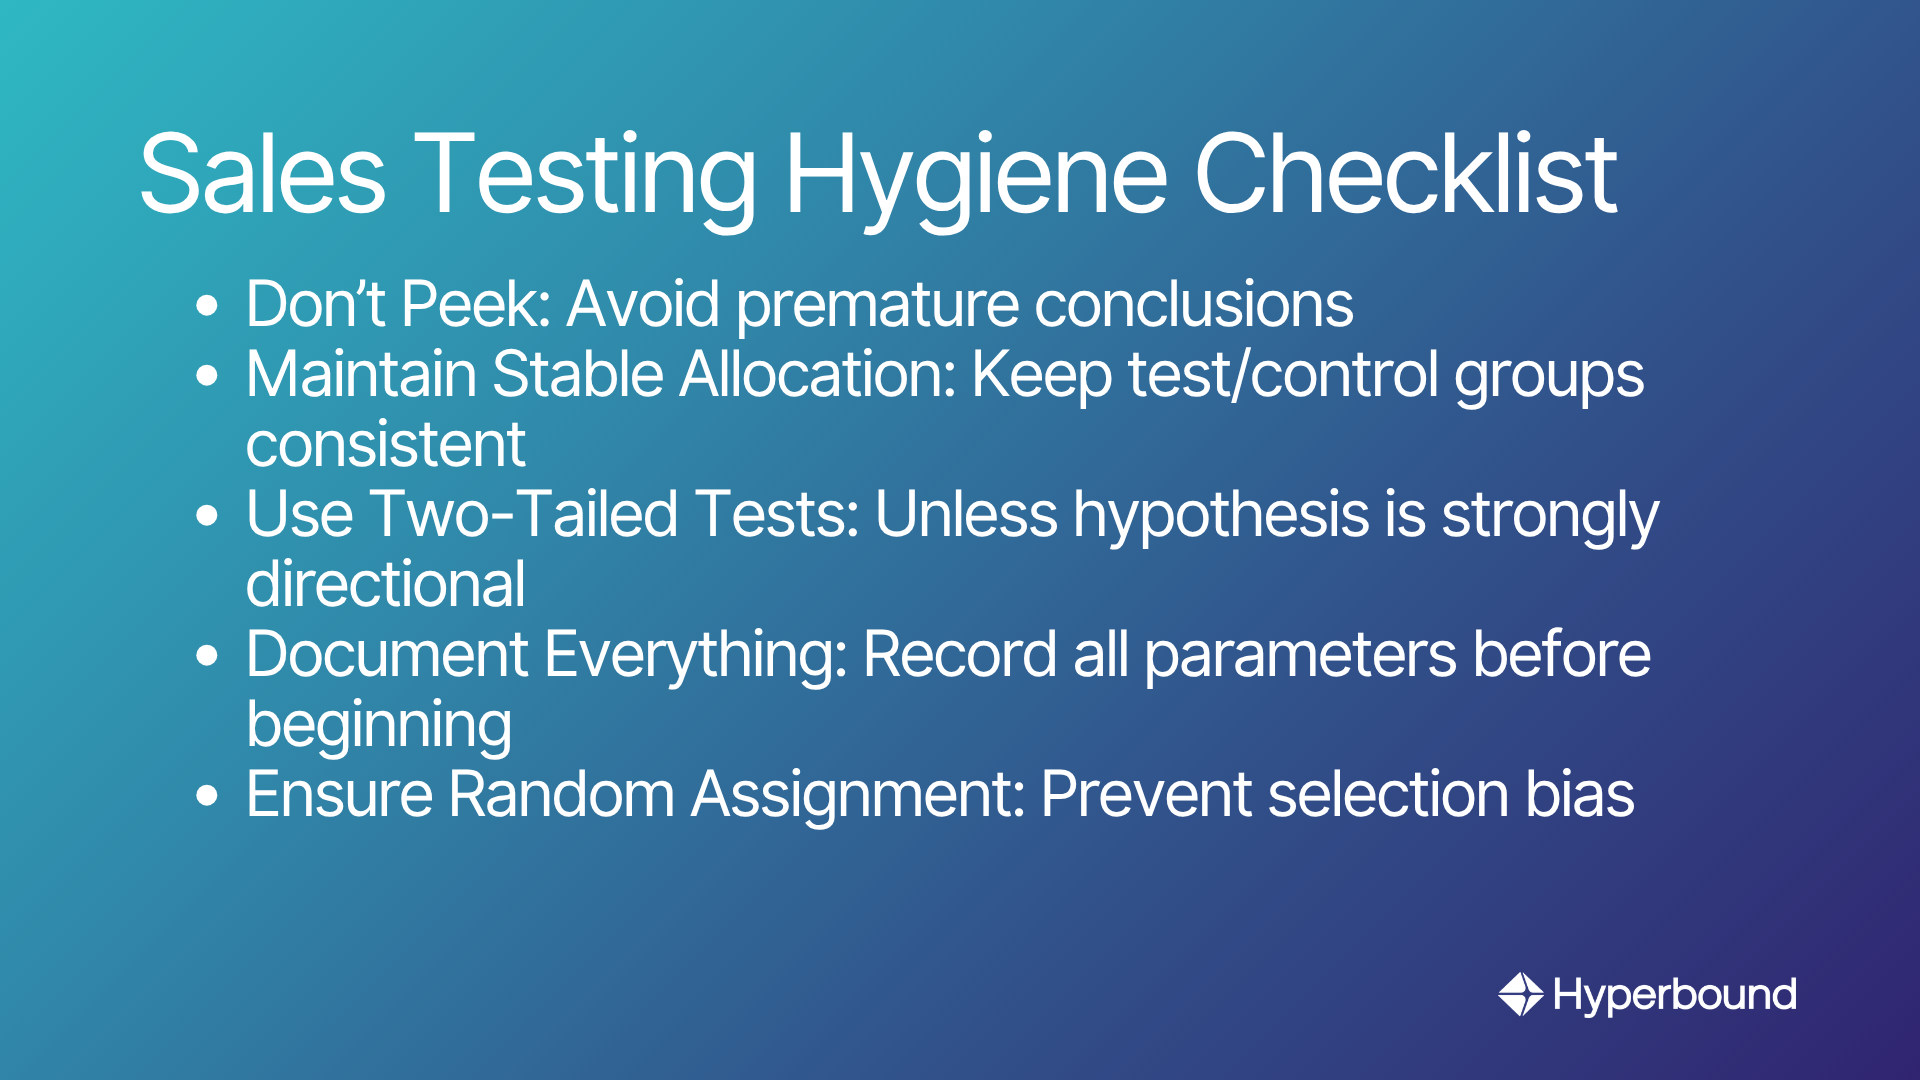
To maintain validity in your multi-segment sales testing:
For teams starting with no conversion data, consider this three-phase approach:
Multi-segment testing in sales is powerful but requires statistical discipline to yield reliable results. By planning ahead with power analysis, correcting for multiple comparisons, and being strategic about your testing scope, you can avoid the pitfalls that lead to false conclusions and wasted resources.
Beyond the statistical setup, the validity of your test also depends on consistent execution. If reps deviate from their assigned scripts or fail to handle objections according to the test parameters, your data will be noisy and unreliable. This is where AI-powered tools can provide a critical advantage. For instance, platforms like Hyperbound allow reps to practice new talk tracks in realistic AI roleplays before going live. This ensures they master the messaging for each segment, leading to higher-quality execution and more reliable test results. Furthermore, with AI Real Call Scoring, you can objectively measure adherence to your playbook across both test and control groups, ensuring the differences you measure are due to the strategy, not inconsistent performance.
Remember that every properly designed test, whether it confirms or rejects your hypothesis, provides valuable data that makes your next sales campaign more effective. This creates a continuous learning loop that transforms your outbound calling efforts from guesswork to a data-driven engine for growth.
By implementing these statistical best practices, you'll gain confidence in your test results and ensure that your sales strategies are truly optimized for each customer segment, maximizing both conversion rates and lifetime value (LTV) for your business.
As you refine your approach to testing across segments, you'll discover not just which sales scripts convert best overall, but which specific messaging resonates with each portion of your market—turning statistical significance into significant business results.
The multi-segment testing trap is the common mistake of drawing false conclusions because the risk of finding a misleading "winner" (a false positive) increases dramatically as you test more customer segments simultaneously. Each segment you test is a separate experiment. Without adjusting your statistical methods, running 10 tests at a 95% confidence level gives you a 40% chance of at least one result being a fluke, leading you to invest in a sales strategy that isn't actually effective.
Testing more segments increases risk due to the "multiple comparisons problem." Each test has a small chance of being wrong (typically 5%), and these chances add up with every new segment, making it highly probable that at least one of your "significant" findings is just random noise. Think of it like this: the more statistical "flips" you do by testing segments, the higher the likelihood of a random chance result appearing significant.
You can determine if you have enough prospects by conducting a power analysis before you start your test. This calculation tells you the minimum sample size required for each segment to reliably detect a meaningful difference in conversion rates. If the required sample size per segment exceeds the number of prospects you have, you should reduce the number of segments you test to maintain statistical validity.
The Bonferroni correction is a method used to counteract the multiple comparisons problem by making your test for statistical significance more strict. You simply divide your initial significance level (e.g., 0.05) by the number of segments you are testing. For example, if you test 5 segments, your new significance level becomes 0.01. A result is only considered significant if its p-value is below 0.01, which drastically reduces your chances of acting on a false positive.
If you have no baseline data, start with a simple A/B test on your entire prospect list instead of segmenting. The goal of this first phase is to establish a reliable baseline conversion rate and identify a winning strategy that can serve as your control for future, more targeted tests. This phased approach prevents you from getting lost in statistical noise when you don't have a starting benchmark.
Yes, segmenting results after a test is a poor practice known as "data dredging" or "p-hacking." It dramatically increases the risk of finding false positives because you are running multiple unplanned tests until you find a pattern, which is likely just random chance. Always define your segments and hypotheses before the test begins to ensure you are testing a deliberate strategy.











Use Cases
Legal