
You invested in AI call scoring. You connected it to your call recorder, watched the dashboards populate with data, and waited for your team's numbers to climb.
They didn't.
Sound familiar? You're not alone. Across sales floors everywhere, managers are sitting on mountains of conversation intelligence and seeing almost zero change in rep behavior or win rates. The tool is working. The framework isn't.
And here's the uncomfortable truth the vendors won't tell you: the technology is not the hard part. Dropping an AI scoring tool into a team that doesn't have a coaching-ready foundation is like installing a high-performance engine in a car with no steering wheel. You'll go fast, but not anywhere useful.
The real problem — as sales reps themselves will tell you — is that AI tools have been poorly deployed. Reps complain that AI role-play is an "absolute waste of time" that "does not translate at all to real world with a real live prospect." Live coaching tools generate long delays that "completely kill the conversation and make it feel robotic." The skepticism is earned. And it isn't about the AI — it's about the lack of strategic context around it.
The good news? There's a fix. Before you turn on any AI call scoring tool, you need to build the framework that makes scoring matter. Here are the four steps to do it.
Before you can score a call, you need a rubric — and a generic rubric is nearly worthless. Your definition of an excellent call has to be anchored in the specific sales methodology your team actually uses.
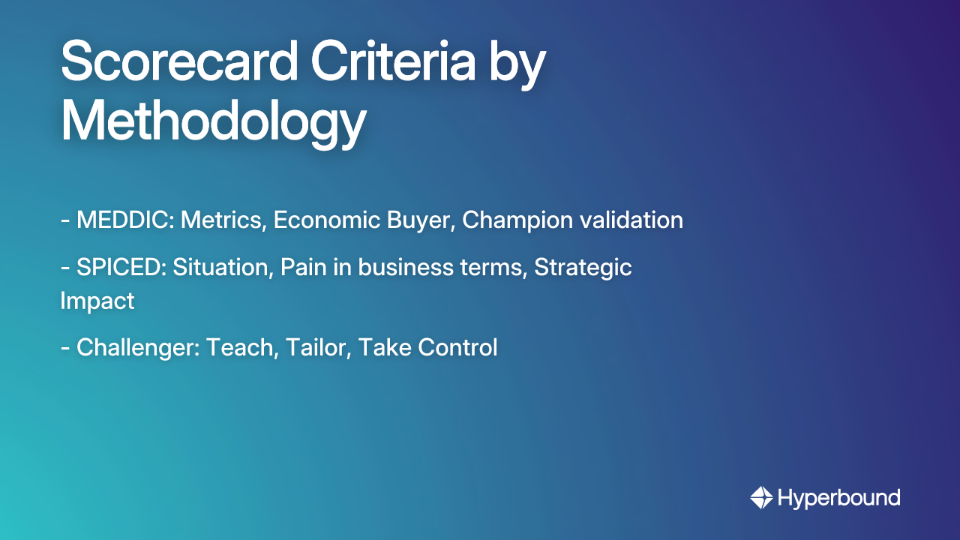
If your team runs MEDDIC, your scorecard criteria should ask:
If your team runs SPICED, your criteria should include:
If your team uses Challenger, your scorecard should evaluate:
This is the step most teams skip. They implement AI call scoring with out-of-the-box templates and wonder why scores don't move the needle — because the criteria weren't meaningful to begin with. While some call scoring checklists can be a useful reference point, they should be a starting line, not the finish line.
A great discovery call is not the same as a great negotiation call. Your scoring framework needs to reflect where in the deal lifecycle a conversation is happening — because the objective of each stage is completely different.
Here's what stage-specific scoring looks like in practice:
Discovery Call Scorecard: High weight on the number of open-ended discovery questions asked, whether the rep uncovered at least 2–3 distinct business pains, and whether clear, qualified next steps were confirmed.
Demo Call Scorecard: High weight on whether the rep connected product capabilities directly to previously identified pains, how effectively they handled objections with value-based responses, and whether they secured commitment from a key stakeholder for the next meeting.
Negotiation / Late-Stage Call Scorecard: High weight on the rep's ability to defend pricing with articulated value, how they navigated procurement or legal pushback, and whether a mutual action plan with a hard close date was established.
This stage-specific approach directly addresses a real-world pain point: sales teams overwhelmingly agree that "we don't do demos unless we know a lot about the customer and what they're trying to accomplish." A strong discovery scorecard enforces that standard before deals ever advance.
A score without a conversation is just a grade. A score with a coaching conversation is a turning point. Data doesn't change behavior — the manager's application of that data does.
SalesGrowth.com outlines a four-part coaching cadence that maps perfectly onto an AI-assisted coaching model:
The cadence creates the conditions for coaching to land. But it only works if you've done steps one and two first.
This is where most coaching programs quietly fall apart. They identify the gaps. They have the conversations. But they don't have a systematic, repeatable way to actually close those gaps. The insight evaporates between the 1:1 and the rep's next live call.
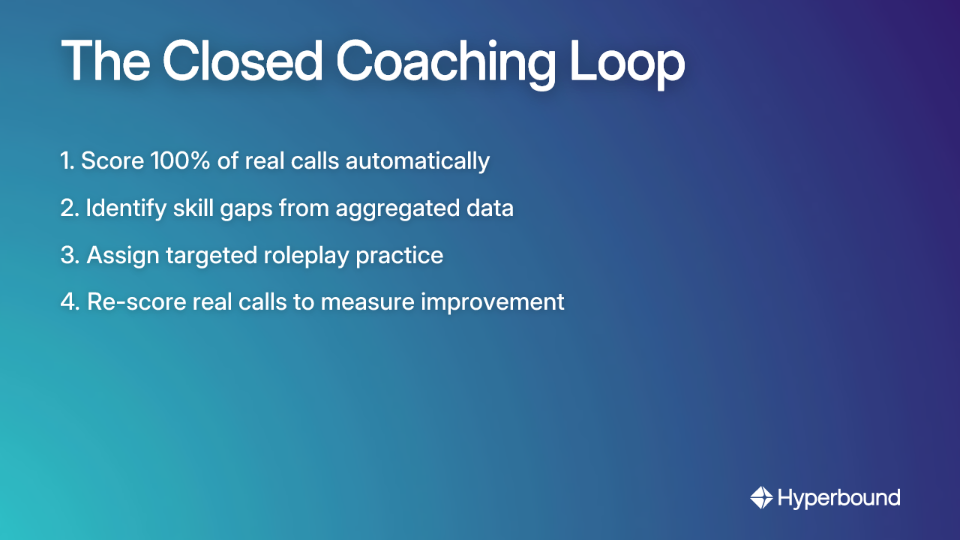
The fix is building a closed operational loop:
Score Real Calls → Identify Skill Gaps → Practice Roleplays → Score Real Calls Again
This isn't a one-time exercise. It's a continuous improvement cycle. Each rotation of the loop tightens rep execution and surfaces new areas to work on. Here's what each stage demands:
Here's a ready-to-use scorecard template for a discovery call, built around the criteria framework from Step 1. Customize the weights to match your methodology's priorities.

Use this as your baseline. As you build stage-specific scorecards (Step 2), replicate the format and adjust criteria and weights to reflect what matters most at each stage of your pipeline.
Once your framework is defined, the right technology should operationalize it — not replace it. Here's how Hyperbound's product suite maps to each phase of the loop:
Hyperbound Perform handles the scoring and intelligence layer. It automatically scores 100% of real customer conversations against the custom methodology scorecards you've built — integrating with Salesloft, Chorus, and other recording tools you already use. Critically, Perform analyzes across the entire deal lifecycle, not just individual calls. This gives you a true read on deal health grounded in actual rep behavior, not CRM field hygiene. It surfaces where deals are at risk and which skill gaps are showing up across your pipeline — the "Identify Skill Gaps" engine of the loop.
Hyperbound Practice closes the loop with targeted roleplay. Once Perform identifies a gap — say, a rep consistently failing to quantify impact before moving to demo — a manager can assign a targeted practice session built around that exact scenario. This is where the skepticism about AI roleplay gets addressed head-on: Practice's AI buyer personas are built from analysis of 2M+ hours of real B2B sales conversations. The simulations aren't generic scripts. They're realistic because they're grounded in how real buyers actually respond — which is why reps who practice with purpose, against relevant scenarios, develop skills that actually transfer to live calls.
Kota sits above both products as the orchestration layer. Think of Kota as your AI Revenue Analyst. Rather than requiring managers to manually connect the dots between scorecard data and practice assignments, Kota does that work — recommending the right coaching intervention for the right rep at the right moment. It turns the operational loop from a manual process into an automated, continuously running system. The result is that coaching interventions happen based on real signals, not gut feel or whoever happened to get a call reviewed this week.
Most teams implement AI call scoring and then wait for the results to materialize. They don't. Data doesn't coach. A framework does.
The four steps — defining what good looks like for your methodology, mapping criteria to deal stages, establishing a feedback cadence, and connecting scores to targeted practice — are the foundation. Without them, AI scoring is just a reporting layer. With them, it becomes the engine of a continuous improvement loop that gets better every cycle.
This is what Revenue Activation means in practice: closing the gap between analyzing what happened on a call and actually changing what happens on the next one. The technology exists to automate the scoring, surface the gaps, power the practice, and orchestrate the interventions. The framework is what makes all of it matter.
Build the foundation first. Then turn on the tools.
Your AI call scoring tool is likely not improving performance because it was implemented without a strong, underlying coaching framework. The technology provides data, but it cannot change rep behavior on its own. For the scores to be meaningful, they must be tied to a clear definition of a "good call" based on your sales methodology, mapped to specific deal stages, and used within a consistent coaching cadence that includes targeted practice.
To create an effective sales call scorecard, you must anchor its criteria in your team's specific sales methodology (e.g., MEDDIC, SPICED, Challenger) and tailor it to the deal stage of the call. A generic, out-of-the-box template is not enough. First, define the key behaviors for your methodology. Then, create distinct scorecards for stages like discovery, demo, and negotiation, as the objectives for each are completely different.
You should always define your coaching framework before implementing an AI call scoring tool. The tool is meant to automate and scale your coaching strategy, not create one for you. By first defining what a "good" call looks like, mapping criteria to deal stages, and planning your feedback cadence, you ensure the technology will be configured to support your specific goals from day one, avoiding the common pitfall of having a powerful tool with no clear purpose.
To ensure rep adoption, involve them in the process of creating the scorecards and transparently connect the scores to constructive, developmental coaching. Reps often distrust AI tools when they feel the criteria are generic or irrelevant. By building scorecards around your team's actual sales methodology and using the data for supportive coaching—not just as a grading tool—you demonstrate that the system is there to help them win more deals.
A closed coaching loop is a continuous cycle of scoring real calls, identifying skill gaps from the aggregated data, assigning targeted practice (like AI role-plays) to address those gaps, and then re-scoring future calls to measure improvement. This loop is crucial because it systematically connects analysis to action. It ensures insights from call scoring lead to tangible skill development, preventing the same mistakes from being repeated.
AI call scoring is the technology that automatically analyzes and rates conversations to provide data on performance. A coaching framework is the human-led process that uses that data to drive behavior change. AI scoring provides the "what" (e.g., a low score on objection handling), while the coaching framework provides the "so what" and "now what," including 1:1s, manager prescriptions, and a system for targeted practice.










Use Cases
Legal